JEV GUIDE · LEARN
Что такое Jev?
Jev is the first System One model from TypeSafe AI, released on 15 September 2026. You send it text and typed questions about that text. It returns typed answers, a probability for each option, and a confidence score.
Updated 19 Sep 2026
How a call works
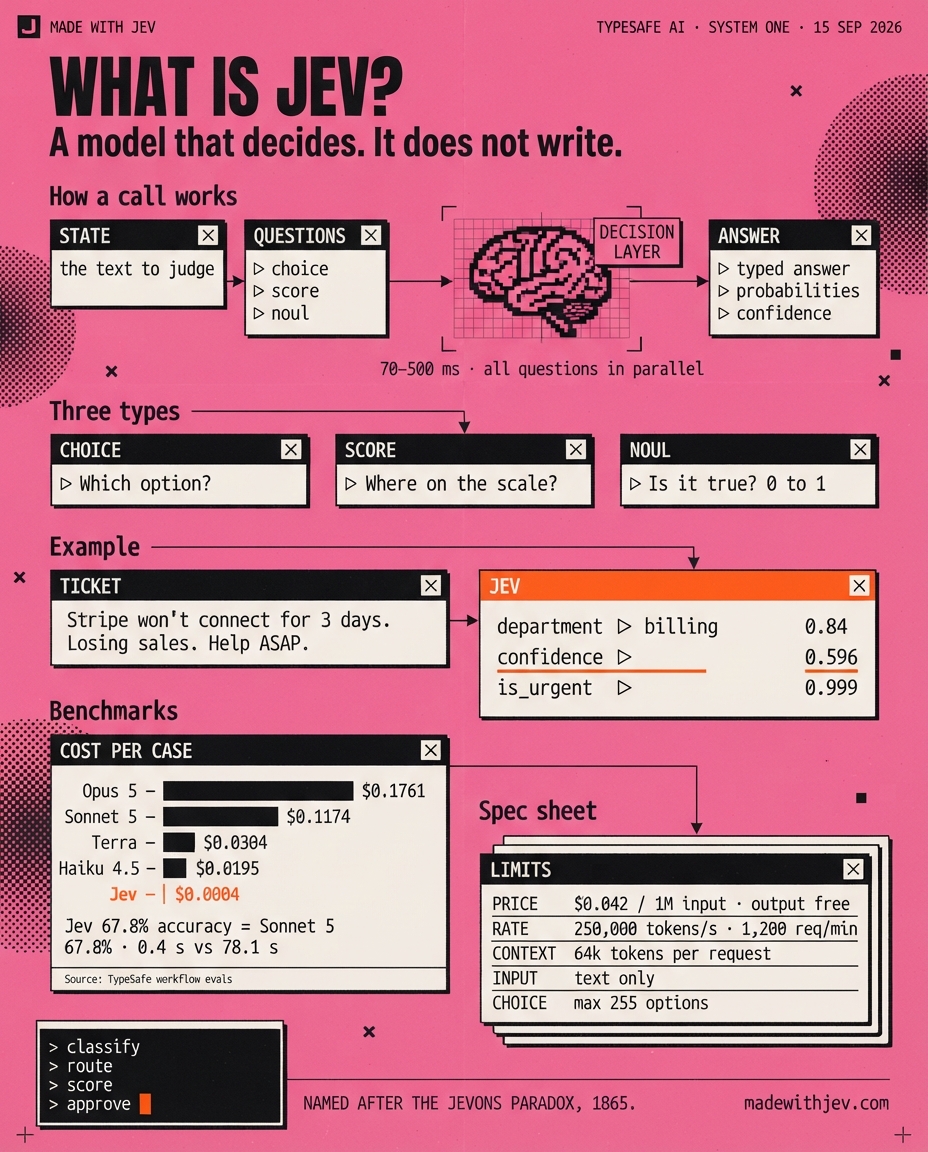
A call has two parts: the state, which is the text to judge, and the questions about it. There are three question types, and one call can mix them. Jev answers all the questions in parallel against the same state, so 60 questions cost about the same as one.
| Type | Asks | Returns |
|---|---|---|
| Choice | Which of these options? | The chosen option, a probability for each, and a confidence |
| Score | Where on this scale? | A level, a probability for each level, and a confidence |
| Noul | Is this statement true? | A probability between 0 and 1 |
Here is a support ticket with two questions: which team gets it, and whether it is urgent.
{
  "state": "Hi, I've been trying to connect my Stripe account for 3 days and it keeps failing. I'm losing sales. Please help ASAP.",
  "model": "jev-latest",
  "questions": {
    "department": {
      "type": "choice",
      "instructions": "Which team should handle this",
      "criteria": {
        "billing": "Payment or subscription issues",
        "technical": "Bugs or integration problems",
        "sales": "Pricing or account questions"
      }
    },
    "is_urgent": {
      "type": "noul",
      "instructions": "The message conveys urgency or time-sensitivity"
    }
  }
}{
"department": {
"choice": "billing",
"probabilities": { "billing": 0.84, "technical": 0.159, "sales": 0.001 },
"confidence": 0.596
},
"is_urgent": { "noul": 0.999 }
}Abridged from TypeSafe’s quickstart. Read the department answer closely. Jev picked billing with a probability of 0.84, but its confidence is only 0.596, because technical also got some weight. The probabilities show which option Jev picked. The confidence shows how sure it is, and that is the number your code uses: act on the confident answers automatically, and send the rest to a person or to a larger model.
One detail catches people out: the question ID, such as is_urgent, never reaches the model. Write the whole question in the instructions.
Speed, cost and accuracy
Input costs $0.042 per million tokens. Output is free. Answers take 70 to 500 milliseconds. In TypeSafe’s own workflow evals, Jev matches Sonnet 5 on accuracy (67.8%) at $0.0004 per case, against $0.1174 for Sonnet 5.
| Model | Mean accuracy | Cost per case | Time per case |
|---|---|---|---|
| Opus 5 | 73.1% | $0.1761 | 37.8 s |
| Terra | 67.9% | $0.0304 | 10.1 s |
| Sonnet 5 | 67.8% | $0.1174 | 78.1 s |
| Jev | 67.8% | $0.0004 | 0.4 s |
| Haiku 4.5 | 53.6% | $0.0195 | 12.5 s |
Source: TypeSafe workflow evals. The reference answers come from two large reasoning models, not from people. So 67.8% means Jev agreed with those two models 67.8% of the time. On a time chart Jev’s 0.4 s is almost invisible. On a cost chart, across the same four workflows, it is the short bar.
Models and limits
- Model
- Jev 1.13 (jev-1.13.0). jev-latest points to it.
- Price
- $0.042 per million input tokens. Output is free.
- Rate limits
- 250,000 tokens per second, 1,200 requests per minute
- Context
- 64k tokens per request; 32k for the state plus the longest question
- Input
- Text only: a string, a JSON object, or a list of strings. A Choice holds at most 255 options.
Source: TypeSafe’s models page. The SDKs retry with backoff when a request goes over a limit.
Why it is called Jev
Jev is named after the Jevons paradox. TypeSafe’s founder, Diogo Almeida, wrote that in his launch thread. In 1865, William Stanley Jevons argued that as steam engines used coal more efficiently, Britain would burn more coal, not less. Make a decision cheap enough, and software starts making far more of them.
“System One” comes from Daniel Kahneman’s Thinking, Fast and Slow: System 1 is fast and intuitive, System 2 slow and deliberate. Jev is built for the fast kind.
On 15 September 2026 he wrote that, after co-inventing ChatGPT, he kept asking why superhuman chat models had not led to AGI. Two years in stealth produced a training method, RLCD, and this model: about 20 to 200 times faster, 40 to 400 times cheaper, output tokens free, built for decisions rather than for talk.
What people build with it
One public directory counts 729 builds. Most use Jev in one of a few ways: choosing the next action in an agent, sorting a queue into buckets, scoring every item in a large set, or stopping a risky step unless the confidence is high. The same decision happens many times, so the speed and cost of each one add up. Jev Guide files its own showcases and GitHub projects separately.
- Agents and browsers167
- Benchmarks and evals137
- Open source126
- SDKs and integrations122
- Games and real time74
- Routing and model choice52
- Social feeds51
- Tools and apps51
- Coding and code review39
- Search36
- Context and memory33
- Security and abuse33
- Documents and OCR30
- Trading and markets25
- Inbox and support24
- Ads and marketing24
- Sales and leads15
- Robotics and devices14
- UI14
- SEO and GEO10
- Ecommerce7
Демо Doom в реальном времени на Jev
Игровое демо показывает решения в реальном времени. Диого говорит, что оно делает около десяти вызовов Jev в секунду; в посте есть видео 2:43.
Browser Use + Jev: сверхбыстрый браузерный агент
Gregor Zunic представляет открытый браузерный агент, объединяющий Browser Use и Jev: поиск рейсов за 7 секунд и 0,0039 доллара, с новым пространством действий на каждом шаге, пространством состояний DOM и резервной малой LLM для ввода.

Классификация 1018 статей об ИИ с Jev за $0,08
Автор суммировал каждую статью с помощью DeepSeek V4 Flash, затем передал заголовок, аннотацию и 24 возможные темы в Jev для классификации. Обработано 1018 статей об ИИ при общих затратах $0,08 и медианной сквозной задержке 256 мс на статью.

Мгновенное сжатие контекста с Jev
Пользователь делится идеальным сценарием использования Jev: мгновенное сжатие контекста. Оценивая каждый вызов инструмента и отбрасывая нерелевантное, Jev позволяет сжимать контекст мгновенно, без промптов-суммаризаций.

Where it does not fit
- It does not write text. Drafts, summaries, and code still need an LLM.
- You define the possible answers. A Choice holds at most 255 options.
- Input is text only for now: strings, JSON objects, and lists of strings. No images, audio, or video.
- “Cannot hallucinate” means the answer always has the right type. It can still be wrong. Test the confidence scores on your own data before you choose a threshold.
Watch the founder explain it
Codez shared a 36-minute talk by Diogo Almeida, dated 19 September 2026. The post’s paraphrase: the next era is not the Claude Code or Codex era, which still keeps a human in the loop. The talk puts Jev after that, on the order of 200 times faster and 400 times cheaper, with no value outside the type. The same talk is about why RLHF is no longer the thing. That wording is the poster’s, not a measurement by this site.

Start here
Akshay Pachaar’s plain version: Jev does not generate faster. It does not generate text at all. An LLM writes an answer one token at a time, and even a small JSON object is sequential. Jev evaluates predefined decisions directly, in parallel when they are independent. An agent on a failed deployment may ask whether it is urgent, which team owns it, whether the command is risky, and whether the task is done. With an LLM, the app parses that out of a paragraph. With Jev, you declare the questions. Choice picks engineering, billing, or sales. Score places risk on low, medium, or high. Noul returns the probability that a yes-or-no statement is true. 91% against 9% can route automatically. 52% against 48% should escalate. Code owns the thresholds. Jev is the judgment an if statement cannot pull out of unstructured text. It is not for writing, summaries, code, arithmetic, or a chain of dependent steps. It cannot return an option outside the schema, and it can still pick the wrong valid one.
Nathan Flurry’s hype-free line: Jev does not replace GPT or Claude. It is a very smart switch. It needs a predefined set of options and tells you which one to take. It cannot write code, generate language, show its work, emit an output you did not define, or pick from more than about 255 options at once. It can classify, route, score, rank, attach a confidence, choose a branch or a tool, and label a great many rows. The loop he pictures is: an LLM proposes options, Jev decides, code executes.
Common questions
What is a System One model?
A type of model built for fast decisions that other software uses directly. The name comes from System 1, the fast, intuitive thinking in Daniel Kahneman's Thinking, Fast and Slow. It does not write text, generate code, or explain its reasoning.
Can Jev hallucinate?
It cannot return a value outside the type you asked for, so you never get broken JSON or an invented field. The answer can still be wrong. The confidence score tells you how far to trust it.
What does Jev cost?
Input costs $0.042 per million tokens. Output is free. A response takes 70 to 500 milliseconds.
Does Jev replace an LLM?
No. It handles small decisions that repeat, such as classify, route, score, filter, or approve a tool call. A larger model still writes anything that needs writing.
How do I call it?
With one POST request to TypeSafe's API, or through the Python or JavaScript SDK. You can try a question in the TypeSafe Playground first, without writing code.
What is Jev Engineering?
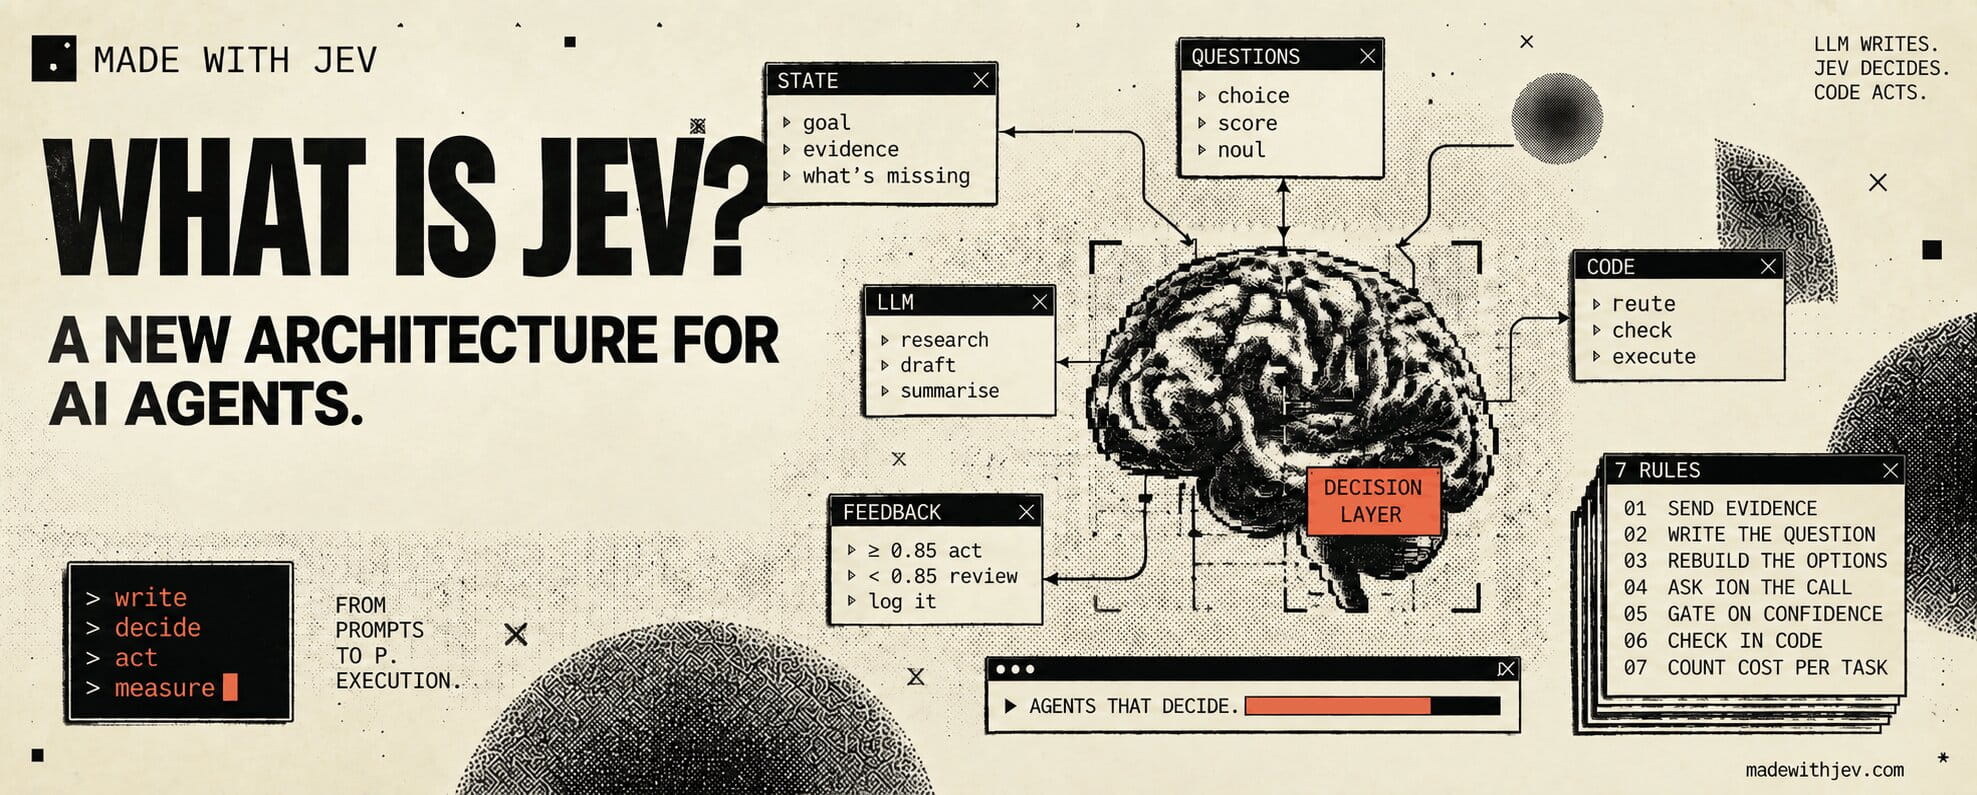
A way to build agents that took off on X three days after launch: an LLM writes, Jev makes the small decisions, and code acts on them.