Jev versus text-generating models
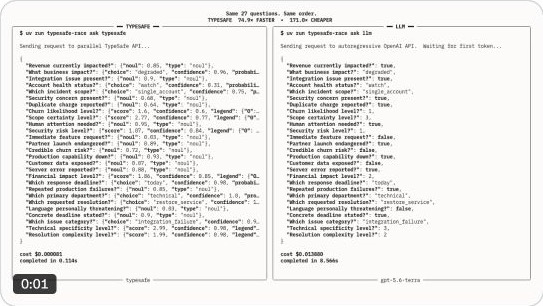
Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
With each model's cutoff set so at most 1 in 100 let-through answers are wrong, Jev lets 93% skip human review, OpenAI 66%, while big general models reach 98% but are about 10× slower.
The number that matters we think: how many answers can skip a human check? With each model's cut-off set so at most 1 in 100 let through are wrong, Jev lets 93% through and OpenAI's 66%. Big general models reach 98%, but they're 10× slower.

Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
The launch thread explains code-and-AI workflow evaluations, the input price announced at launch, and free output tokens.


This model is built for decision-making rather than text generation, outputting probabilities for each option in parallel instead of token-by-token responses. The author shares a simplified comparison of normal LLMs versus this Jev model.
