Jev versus text-generating models
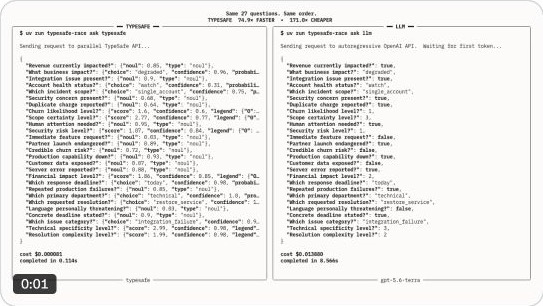
Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
Splitting one vague question into five smaller ones lifts accuracy from 62.6% to 95.0% with the same model. Jev chooses among allowed answers, outperforming Haiku 4.5 when asked granular questions.
ONE BIG QUESTION: 62.6% ACCURATE. FIVE SMALL ONES: 95.0%. SAME MODEL. the whole lesson of this article is in that jump. jev doesn't write. it only picks from answers you allow. ask it one vague question per email and it guesses. split it into 5 small ones and it beats haiku 4.5
Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
The launch thread explains code-and-AI workflow evaluations, the input price announced at launch, and free output tokens.


This model is built for decision-making rather than text generation, outputting probabilities for each option in parallel instead of token-by-token responses. The author shares a simplified comparison of normal LLMs versus this Jev model.
