Jev versus text-generating models
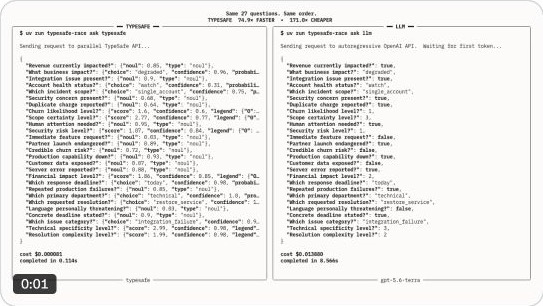
Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
The post says the JEV signal landscape shows how six input sources can be handled in one agent, rather than requiring separate parsers, prompts, and code paths per input.
WHOEVER LEAKED THIS JEV LANDSCAPE OF SIGNALS DESERVES THE CTO SEAT I thought handling six input feeds in one agent meant six parsers, six prompts, and six code paths that disagree in production. Apparently not. This landscape's setup is much more interesting: → SOURCES: 6
Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
The launch thread explains code-and-AI workflow evaluations, the input price announced at launch, and free output tokens.


This model is built for decision-making rather than text generation, outputting probabilities for each option in parallel instead of token-by-token responses. The author shares a simplified comparison of normal LLMs versus this Jev model.
